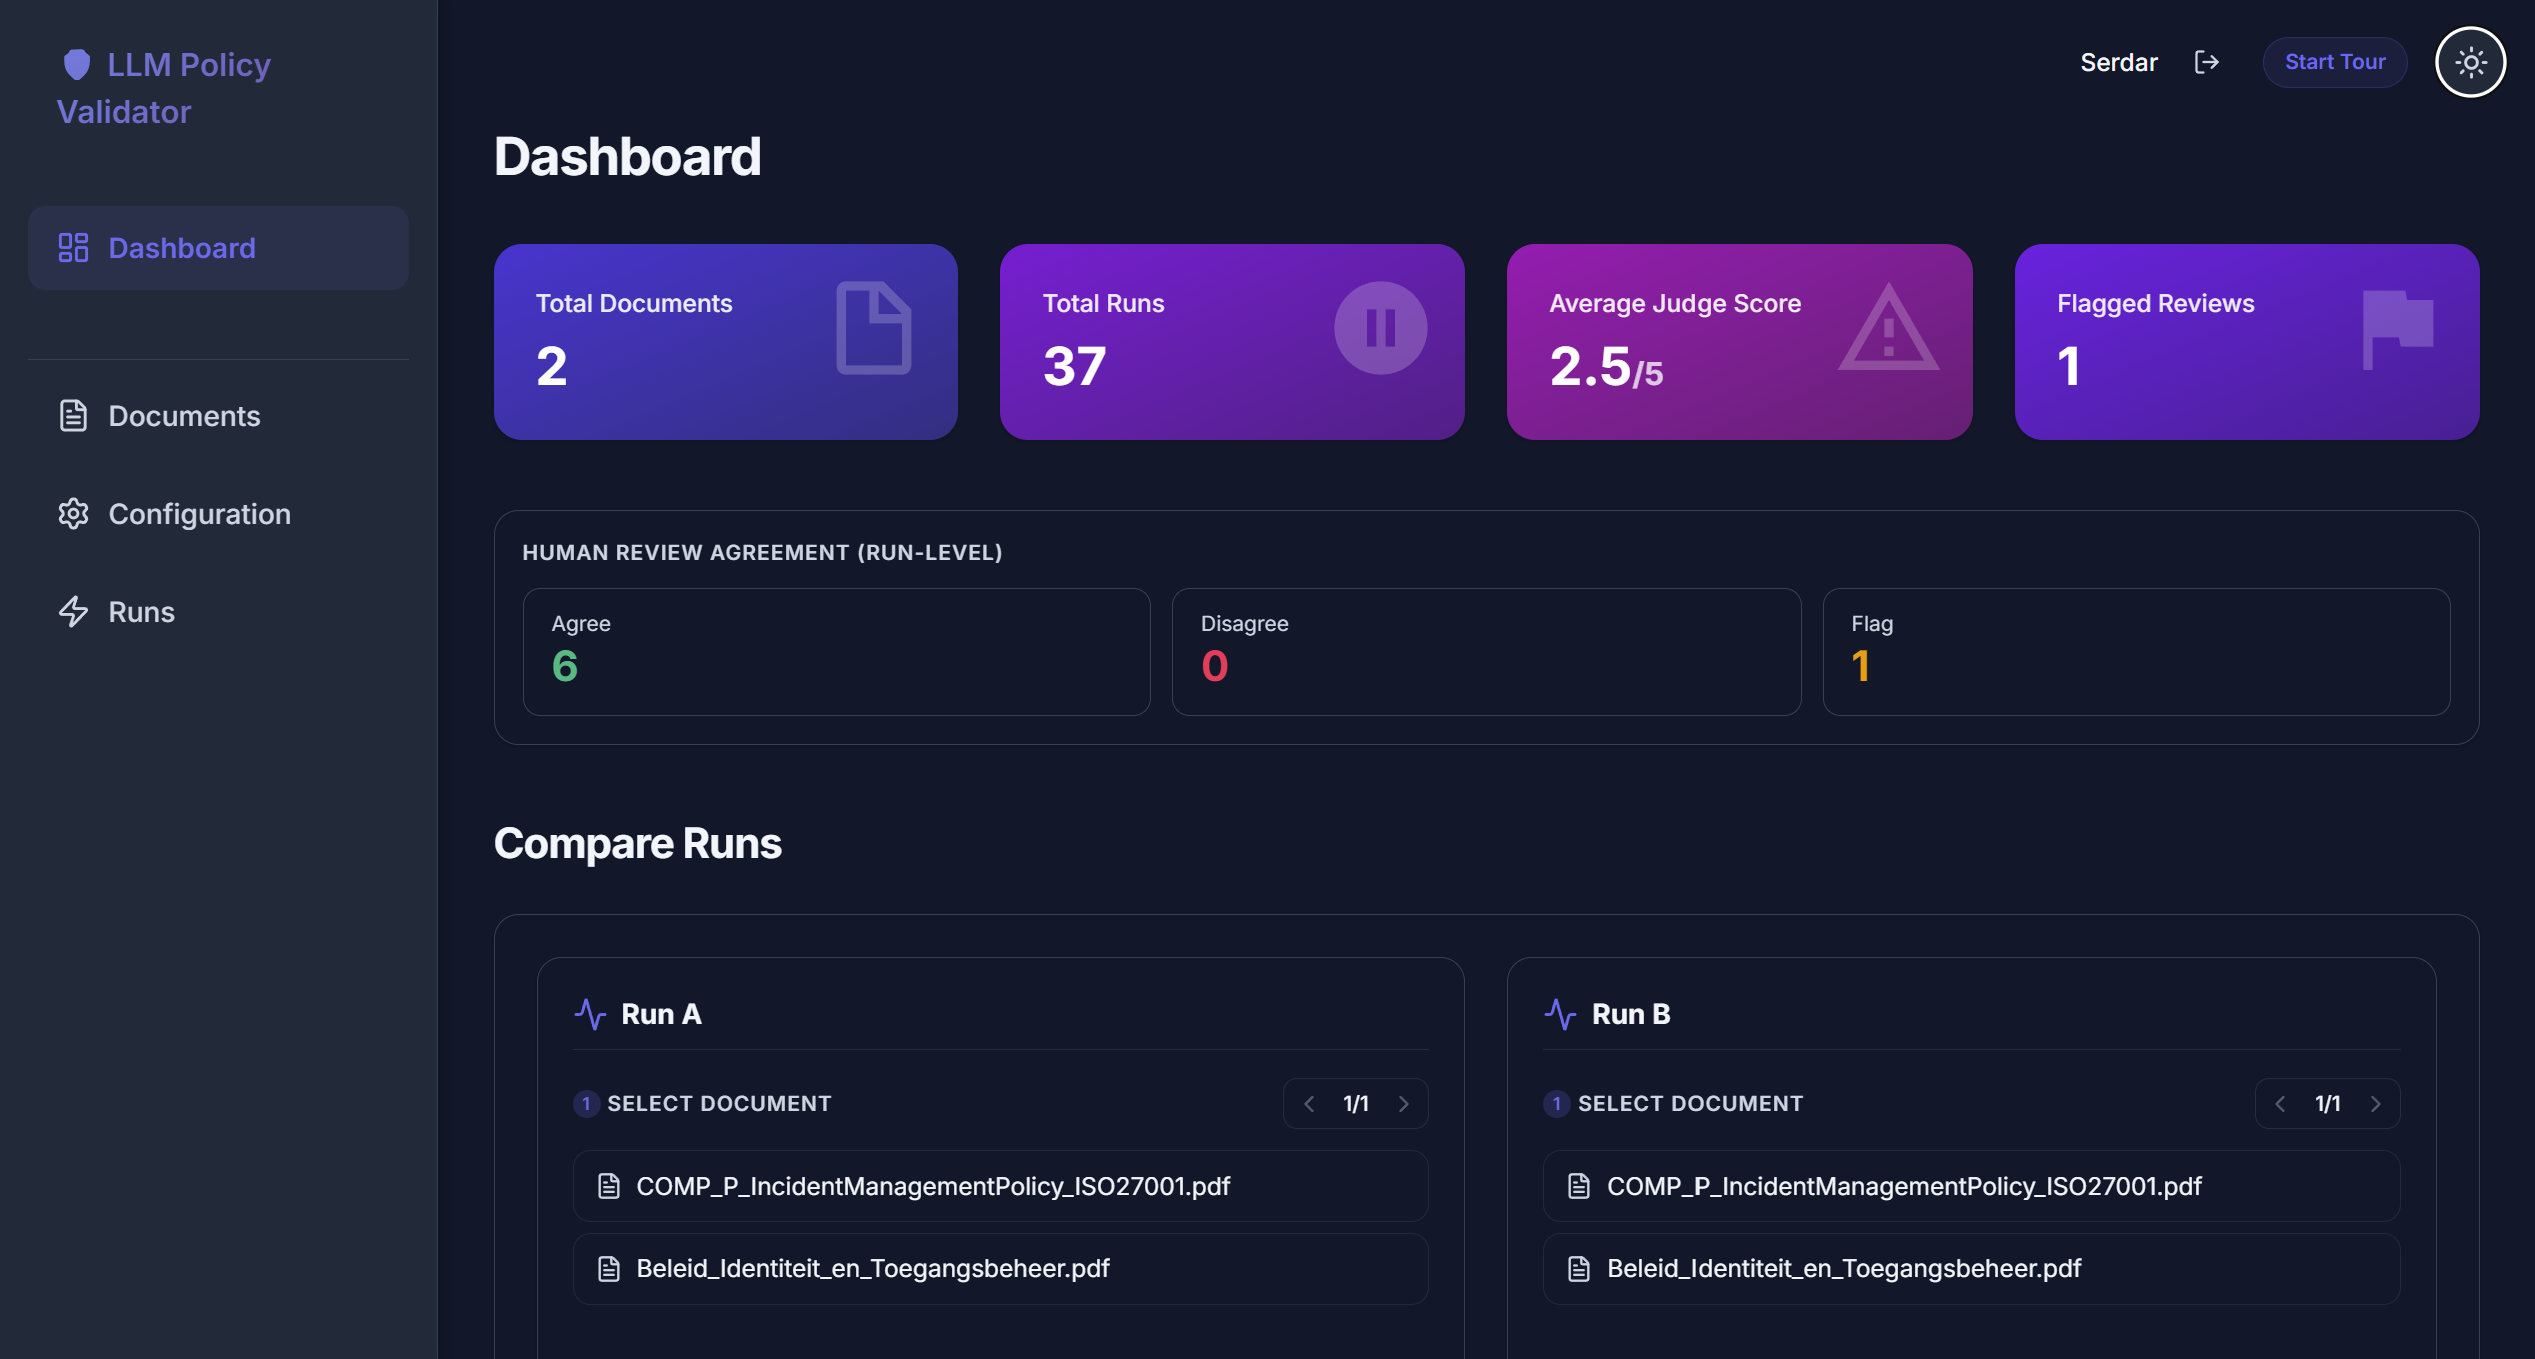
The LLM Policy Validator is my graduation project: an LLM-as-a-Judge framework that tests how reliably AI interprets cybersecurity policies such as ISO 27001 and NIST. A primary language model extracts actionable evidence from uploaded policy documents, after which a second Judge LLM scores every extraction for faithfulness to the source text, classifying it as sound, inference or hallucination. Human reviewers can agree with, dispute or flag each verdict, and a benchmarking module compares the judge's decisions against a human-curated golden set to measure real-world agreement. I built the backend in Python with Flask and PostgreSQL, paired with a Next.js dashboard, turning a research question — can we trust automated validation in a compliance context? — into a working, measurable tool.